Table of contents
The best robots.txt for most Blogger blogs blocks only /search (label and search pages), allows everything else and lists the sitemap. For WordPress, block /wp-admin/, allow admin-ajax.php and add your sitemap URL. Don't block CSS, JavaScript or /wp-content/, because Google needs those files to render your pages.
A wrong robots.txt can quietly hide an entire site from Google, so it's worth five minutes. Below are copy-paste versions for both platforms, what each line does, and how to handle AI crawlers.
What does robots.txt do?
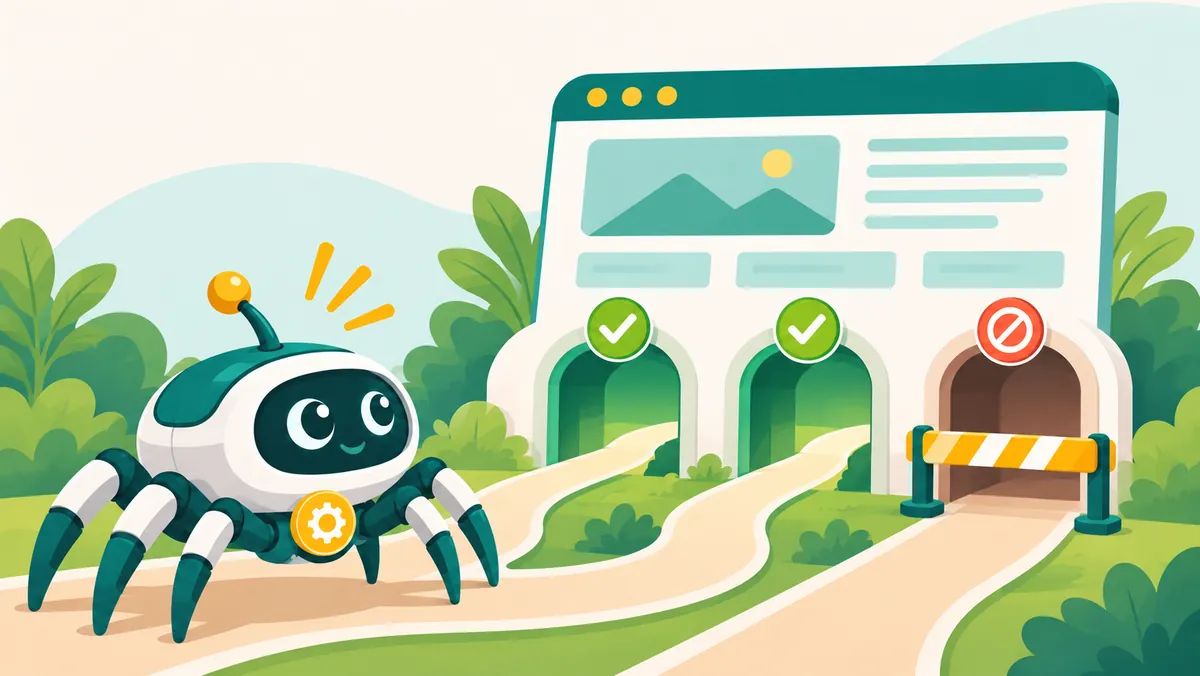
robots.txt is a text file at yoursite.com/robots.txt that tells crawlers which paths they may crawl. It controls crawling, not indexing. A blocked URL can still show up in Google if other pages link to it. To keep a page out of results, let Google crawl it and add a noindex meta tag.
Best robots.txt for Blogger
User-agent: Mediapartners-Google
Disallow:

User-agent: *
Disallow: /search
Allow: /

Sitemap: https://yourblog.blogspot.com/sitemap.xml- Mediapartners-Google is the AdSense crawler. The empty
Disallow:lets it read every page so ads match your content. - Disallow: /search keeps crawlers off label and search pages, which are thin lists that repeat your posts.
- Sitemap points crawlers at every post. Use your custom domain if you have one.
To apply it, go to Blogger → Settings → Crawlers and indexing, switch on Enable custom robots.txt and paste. Leave custom robots header tags off unless you have a specific reason.
Best robots.txt for WordPress
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php

Sitemap: https://example.com/sitemap_index.xml
Use the sitemap your SEO plugin makes. Rank Math and Yoast use /sitemap_index.xml; WordPress without a plugin uses /wp-sitemap.xml. Open the URL in a browser before adding it, to be sure it loads.
WooCommerce stores can also block pages that should never be crawled:
Disallow: /cart/
Disallow: /checkout/
Disallow: /my-account/
Disallow: /*add-to-cart=*
Should you block AI crawlers?
It depends on whether you want AI tools to cite you. AI companies run separate crawlers for training and for search. Blocking a training crawler asks the company not to train on your pages. Blocking a search crawler can stop that tool from citing and linking your pages in its answers.
| Crawler | Company | Used for |
|---|---|---|
| GPTBot | OpenAI | Model training |
| OAI-SearchBot | OpenAI | ChatGPT search results |
| Google-Extended | Gemini training; doesn't affect Google Search | |
| ClaudeBot | Anthropic | Model training |
| Claude-SearchBot | Anthropic | Claude search results |
| PerplexityBot | Perplexity | Perplexity answers |
| CCBot | Common Crawl | Open dataset used for training |
Many bloggers who want traffic take a middle path: block the training-only crawlers and keep the search crawlers allowed.
User-agent: GPTBot
User-agent: Google-Extended
User-agent: CCBot
Disallow: /
This doesn't remove you from Google Search or AI Overviews, which use Googlebot.
5 robots.txt mistakes that hurt rankings
- Leaving
Disallow: /after launch. The whole site stays blocked. - Blocking CSS, JS or
/wp-content/. Google can't render the page properly. - Hiding private pages with robots.txt. The file is public, so you're listing them for anyone.
- Blocking a page that also has noindex. Google can't crawl it, so it never sees the noindex.
- A broken sitemap URL. A 404 there wastes the one hint you give crawlers.
Make yours with the free robots.txt generator, which has Blogger and WordPress presets. If a page still isn't indexed, read how to fix "Discovered, currently not indexed" or test the URL with the index checker.
FAQs
How do I check my current robots.txt?
Open https://yoursite.com/robots.txt in a browser. Google Search Console also has a robots.txt report under Settings.
Can robots.txt affect AdSense?
Yes. If you block Mediapartners-Google, AdSense can't read your pages to match ads. The Blogger version above keeps it allowed.
How fast does Google pick up robots.txt changes?
Google usually caches robots.txt for up to a day, so changes normally show up within 24 hours.